Blog
Engineering reports, system optimizations and model integrations from the RLinf team.
Articles
RLinf × MUSA: Reproducing WoVR on Moore Threads S5000
RLinf Team
- Embodied AI
- System
RLinf x SGLang: Integrating Cosmos3 from Fine-Tuning to Efficient Parallel Evaluation
RLinf Team & SGLang Team
- Embodied AI
- System
RLinf × WorldLoop: Extending WoVR with a Training-Free VLM Reward
RLinf Team
- Embodied AI
Accelerating the "ImageNet Moment" of Embodied AI: RLinf Brings a 25× System Optimization to BEHAVIOR
RLinf Team
- Embodied AI
- System
A First Look at the "Last Mile" of Agent Deployment: Cursor Online Reinforcement Learning
RLinf Team
- Agentic AI
Comparison with VeRL
RLinf Team
- System
No articles match your search.
Papers
 OSDI 2026
RLinf: Flexible and Efficient Large-scale Reinforcement Learning via Macro-to-Micro Flow Transformation
Flexible and efficient RL system.
(opens in a new tab)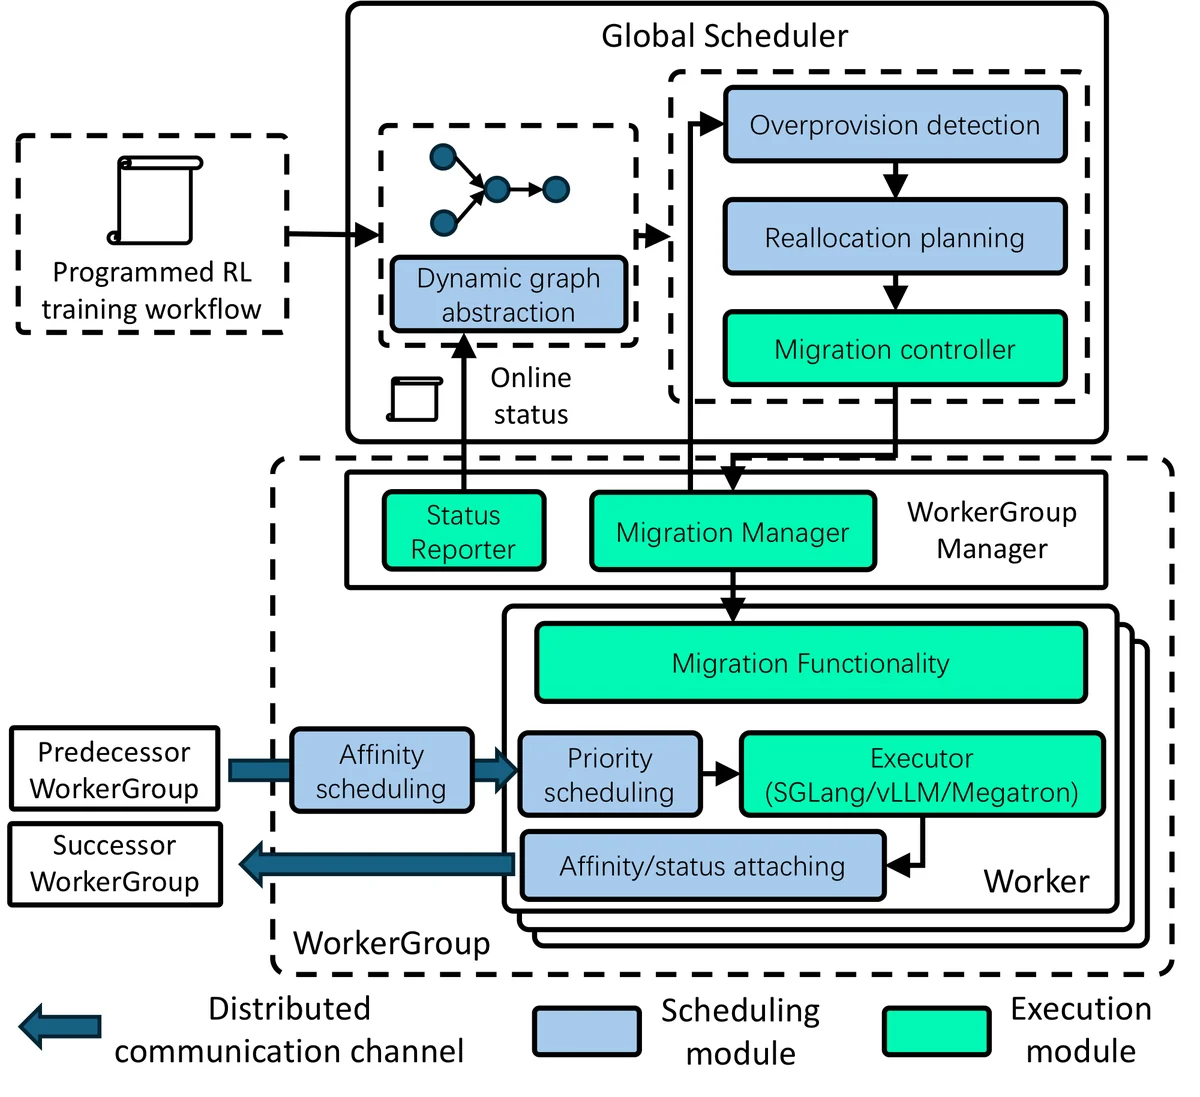 OSDI 2026
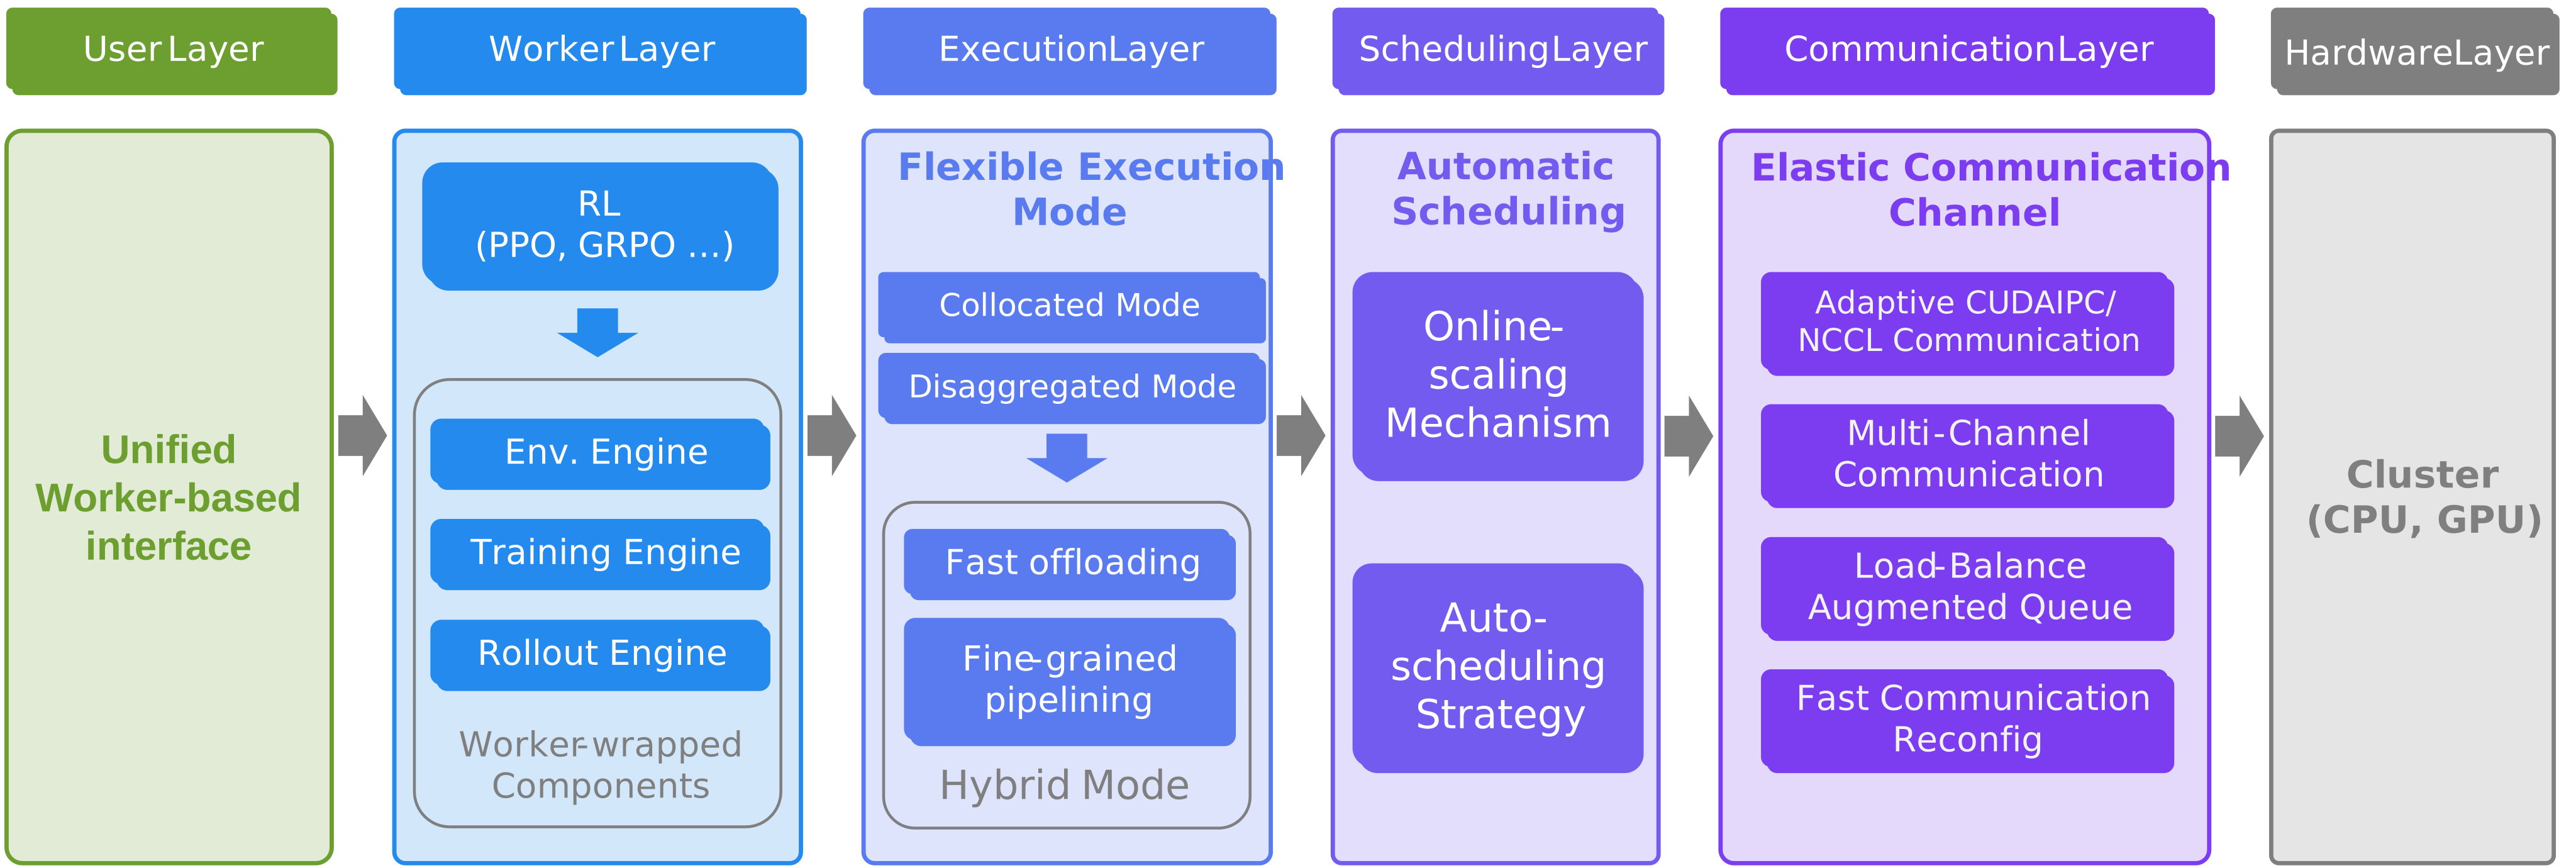
DynaRL: Flexible and Dynamic Scheduling of Large-Scale Reinforcement Learning Training
Flexible and dynamic scheduling for large-scale RL training.
(opens in a new tab)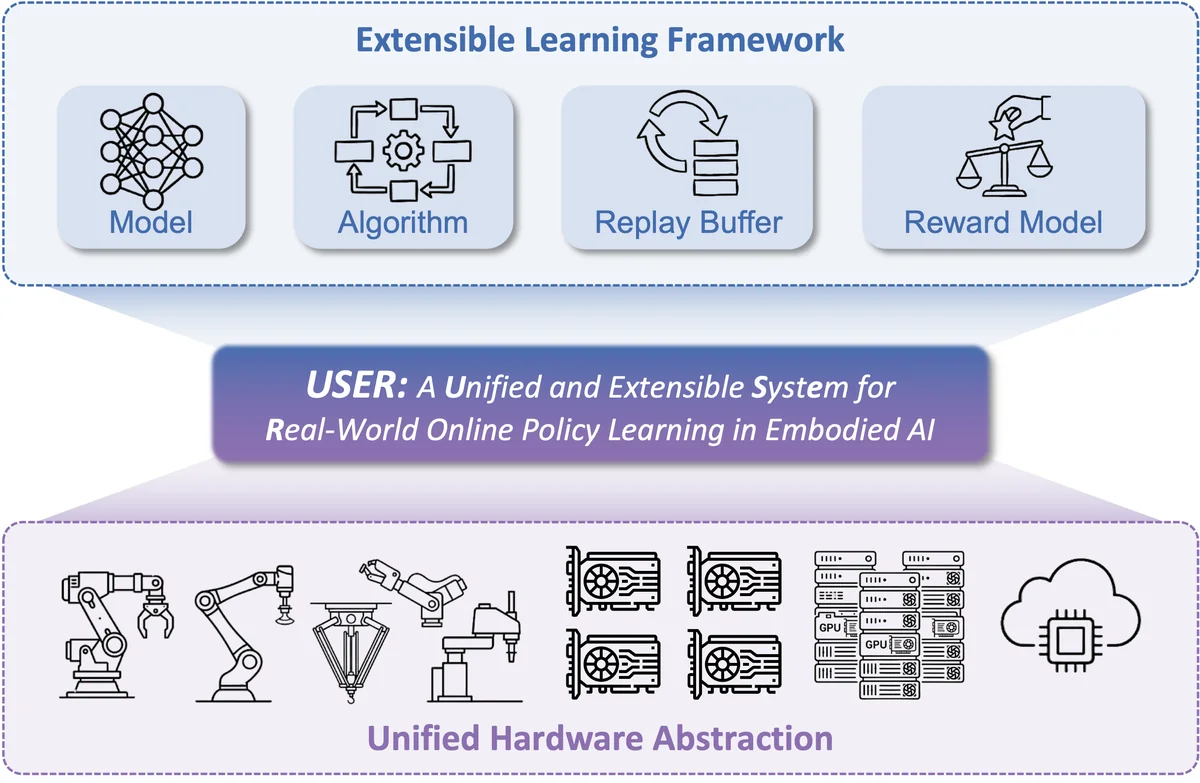 RSS 2026
RLinf-USER: Unified System for Real-world Online Policy Learning
Unified system for real-world online policy learning.
(opens in a new tab)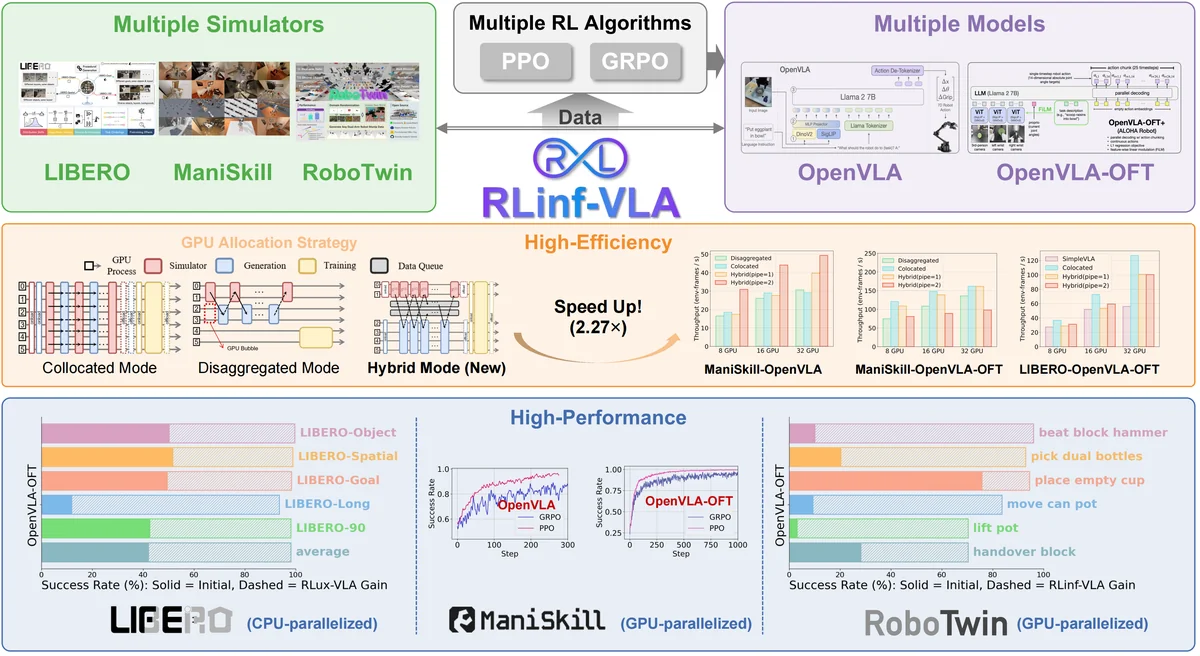 RSS 2026
RLinf-VLA: A Unified and Efficient Framework for VLA+RL Training
Unified framework for VLA+RL training.
(opens in a new tab)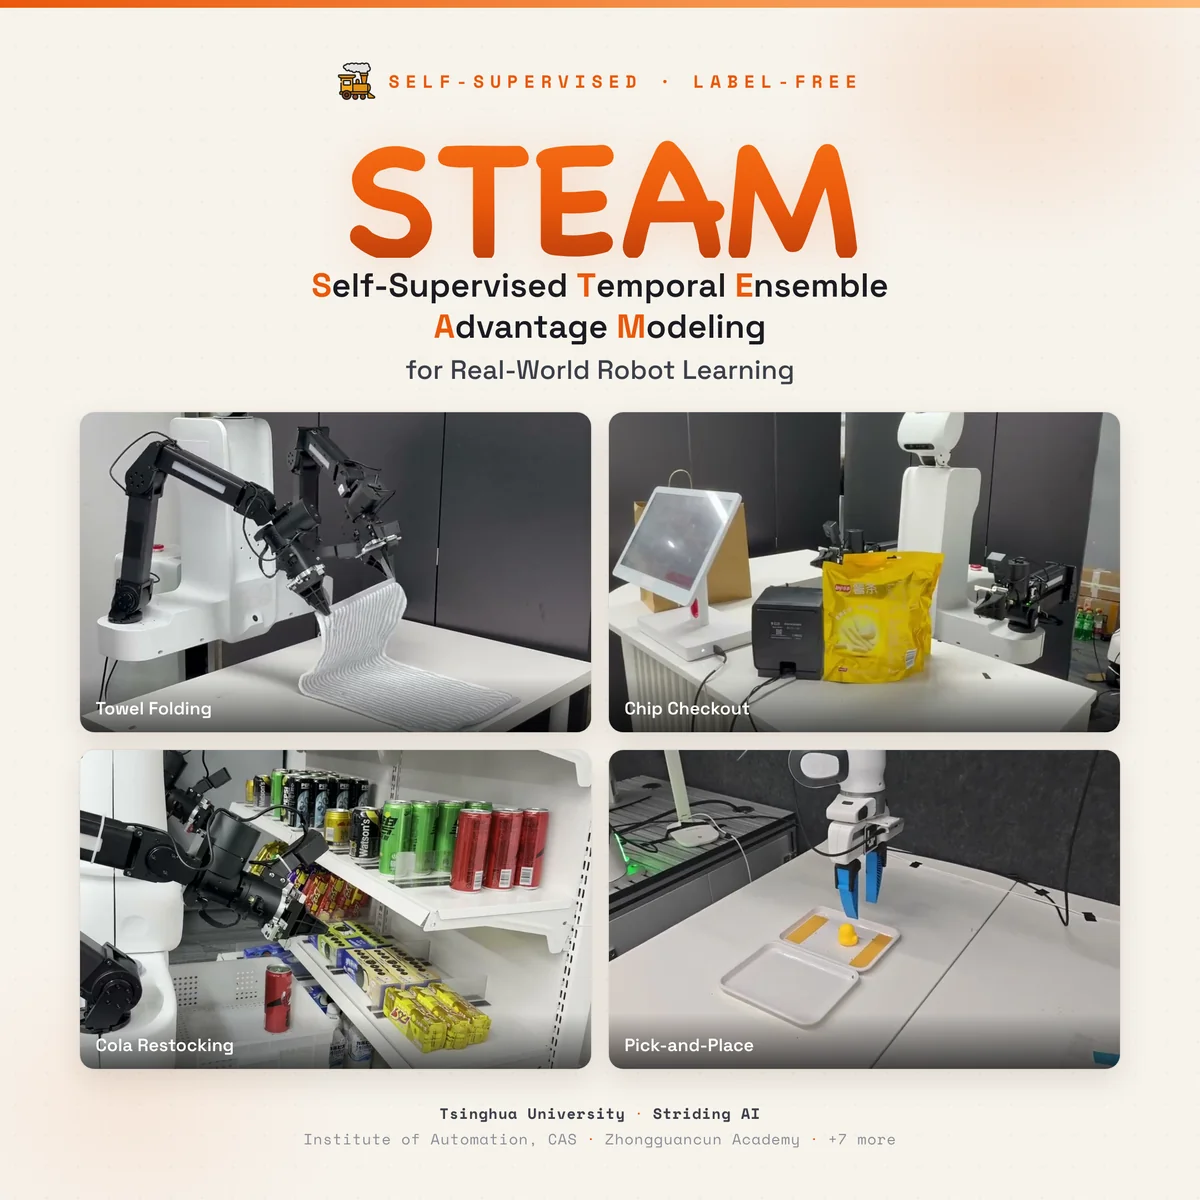 arXiv
STEAM: Self-Supervised Temporal Ensemble Advantage Modeling for Real-World Robot Learning
Self-supervised temporal ensemble advantage modeling for real-world robot learning.
(opens in a new tab)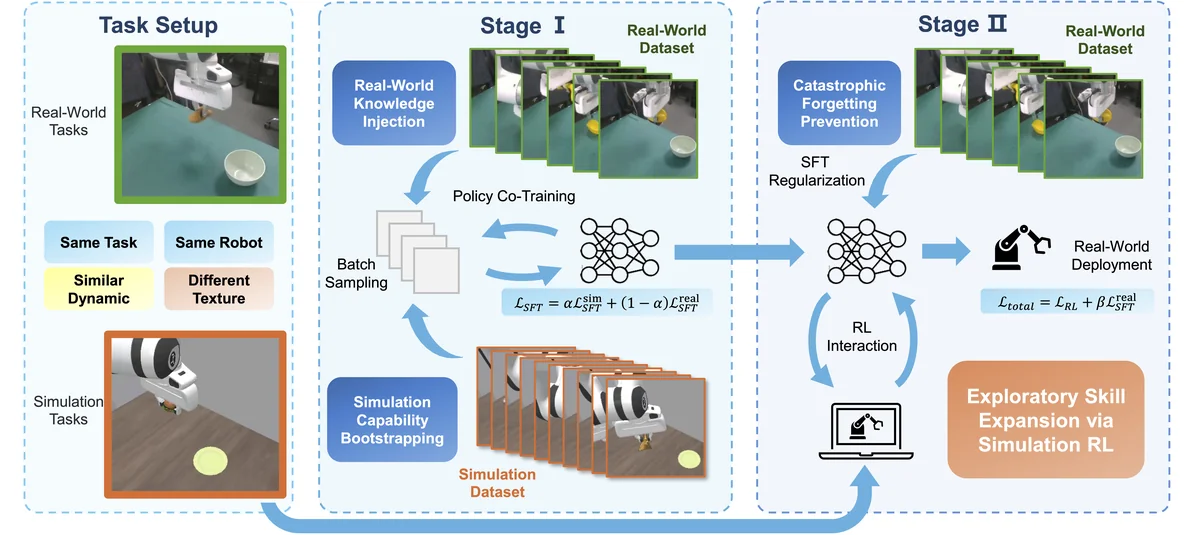 arXiv
Beyond Imitation: Reinforcement Learning-Based Sim-Real Co-Training for VLA Models
Reinforcement learning-based sim-real co-training for VLA models.
(opens in a new tab)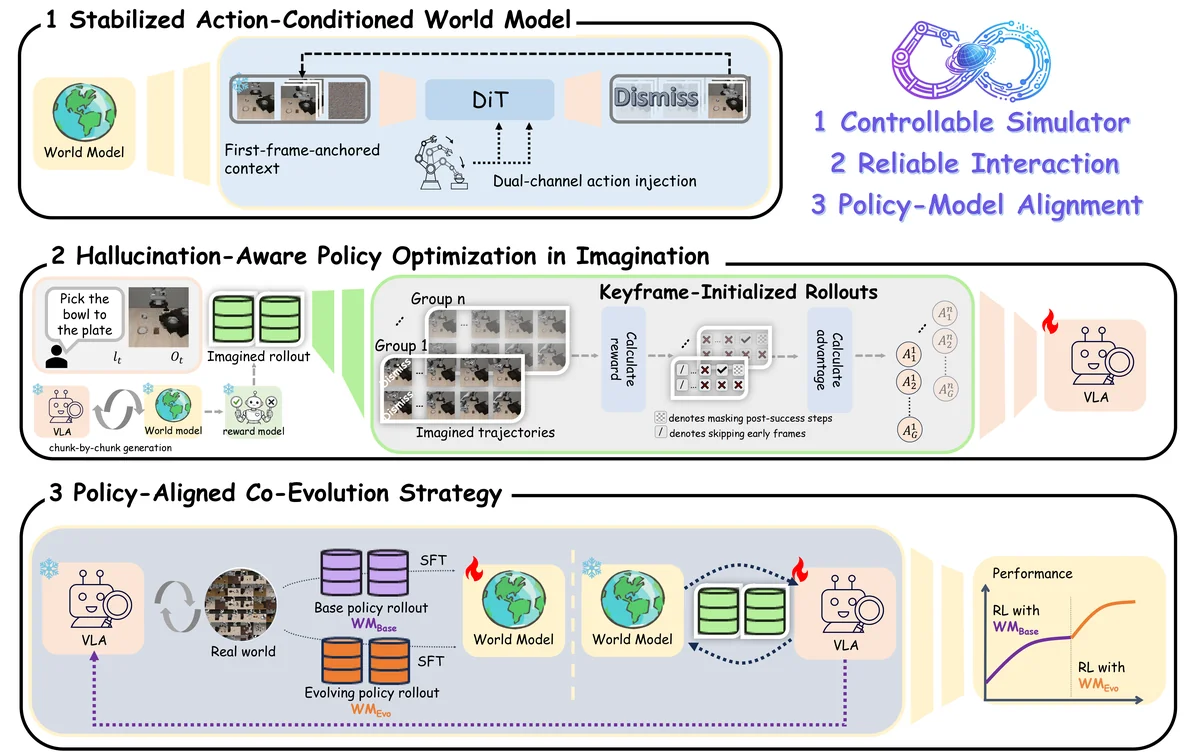 arXiv
WoVR: World Models as Reliable Simulators for Post-Training VLA Policies with RL
World model-based RL fine-tuning for VLA policies.
(opens in a new tab)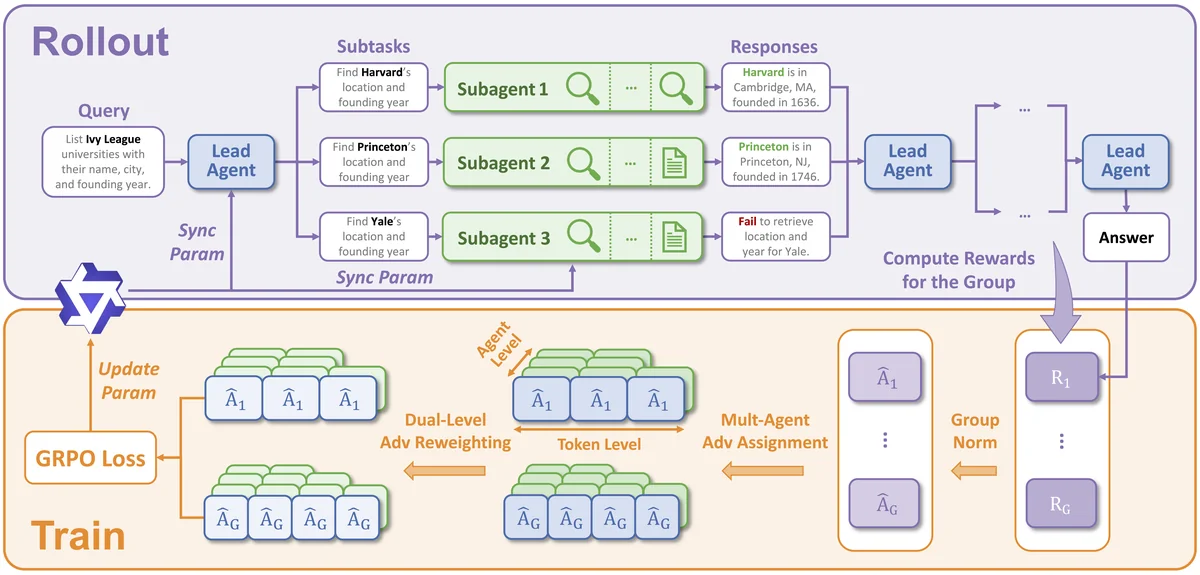 arXiv
WideSeek-R1: Exploring Width Scaling for Broad Information Seeking via Multi-Agent Reinforcement Learning
Exploring width scaling for broad information seeking via multi-agent reinforcement learning.
(opens in a new tab)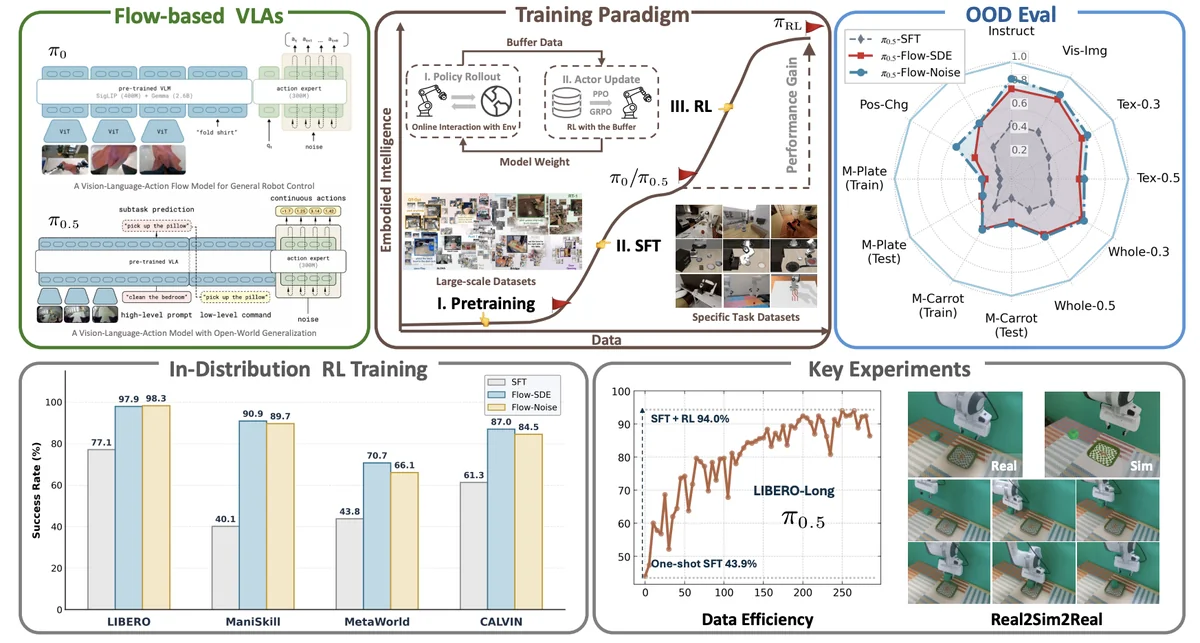 arXiv
πRL: Online RL Fine-tuning for Flow-based Vision-Language-Action Models
Online RL fine-tuning for flow-based VLA models.
(opens in a new tab)
All papers and technical reports in the docs(opens in a new tab)